

LOGGING AND RETENTION
Inference logging is on by default for every deployment, including external deployments. To change it, use the Inference Logging toggle when you create the deployment, or the Inference logging section of the deployment’s Info & Configuration tab. Turn logging off when requests contain data you must not store. Serving metrics and quality monitoring are computed from the logs, so they stop when logging is off. Requests served while logging is off are never recorded, so turning it back on doesn’t recover them. Logs are kept for your plan’s retention period. Older requests are no longer available to read, export, or score.READ THE LOGS
The Inference Logs tab lists one row per request, with its status, a preview of the input and output, the token count, the latency, and the time to first token. Click a row to see the full input and output, the tools the request offered, and the error message if the request failed.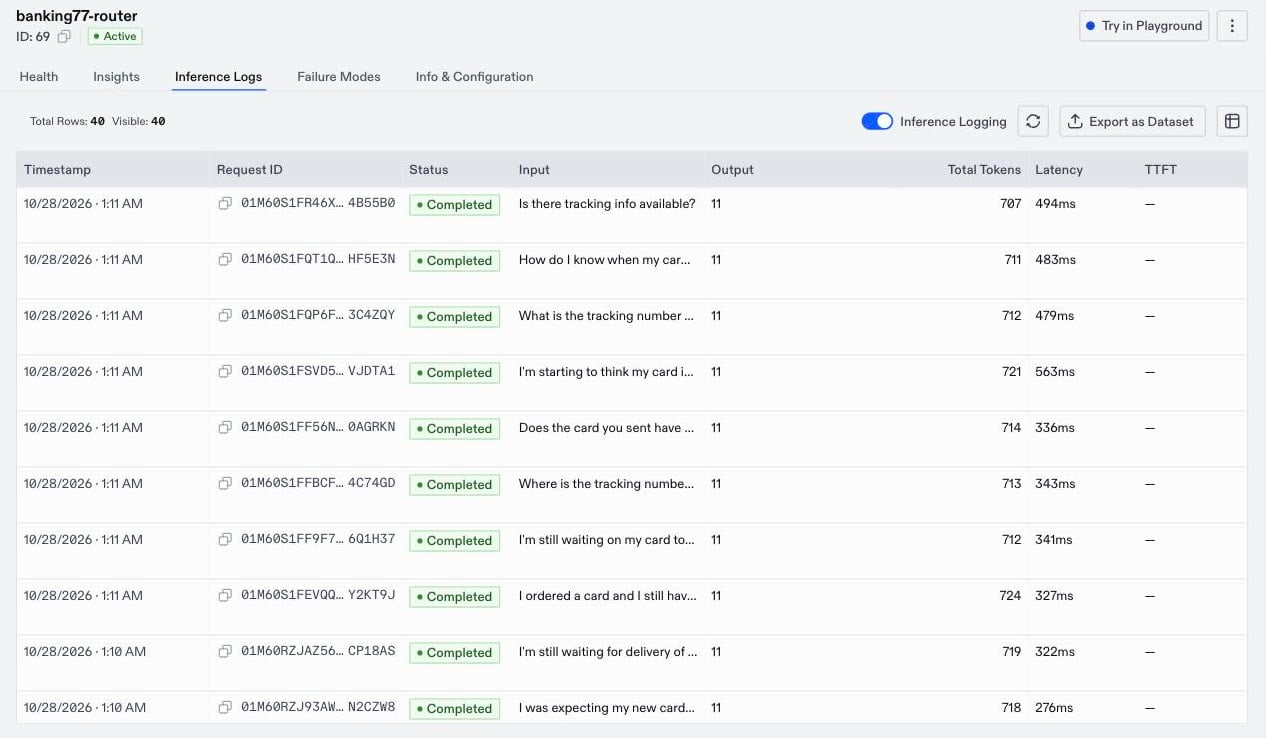
EXPORT LOGS TO A DATASET
Exported logs become a Conversation dataset of user and assistant turns. Use it as a test set that reflects real traffic, as input to synthesis, or as training data.- On the Inference Logs tab, click
Export as Dataset. - Choose
Create new datasetand enter a Dataset Name, or chooseAppend to existingand select a Dataset. - Optionally, set a Start Date and End Date. Leave both empty to include all logs.
- Click
Generate Dataset.