

HOW MONITORING WORKS
A monitor belongs to one deployment. It holds a set of judge evaluators and a sampling rate.- The deployment serves a request, and inference logging records it.
- The monitor picks the share of requests set by the sampling rate.
- Each evaluator scores each picked request. Scoring runs after the response is sent, so it doesn’t slow the deployment.
- The Insights tab plots each evaluator’s scores over time.
WHICH EVALUATORS TO USE
A monitor uses judge evaluators. Production requests have no correct answer stored with them, so choose evaluators that judge the response on its own, such as format, policy, or tone. An evaluator that compares the response with a label in the row’s metadata has nothing to compare against.COST
Every scored request is a judge model call for each evaluator, billed as inference. The cost grows with traffic, the sampling rate, and the number of evaluators. Start at the default 10% sampling rate, and raise it only when a deployment has too little traffic to produce steady trends.SET UP MONITORING
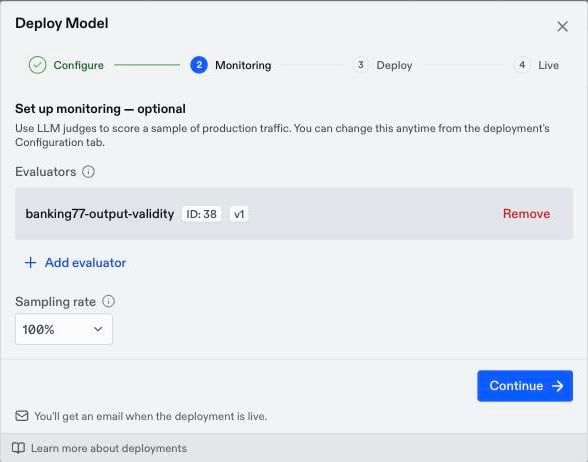
Set up monitoring in any of these ways:- When you deploy: Add evaluators in the Monitoring step of the Deploy Model dialog.
- On a running deployment: On the Info & Configuration tab, go to Monitoring and click
Add evaluator. The first evaluator you add starts the monitor at a 10% sampling rate. - With FAiE (Frontier AI Engineer Agent): Ask FAiE to monitor the deployment. It proposes evaluators and a sampling rate for you to approve.
Stale. To switch to the new version, remove the evaluator and add it again.
READ THE INSIGHTS TAB
The Insights tab shows one chart per evaluator. Each point is the average score of the requests scored in that period, and the pill above the charts shows each evaluator’s average over the whole time window.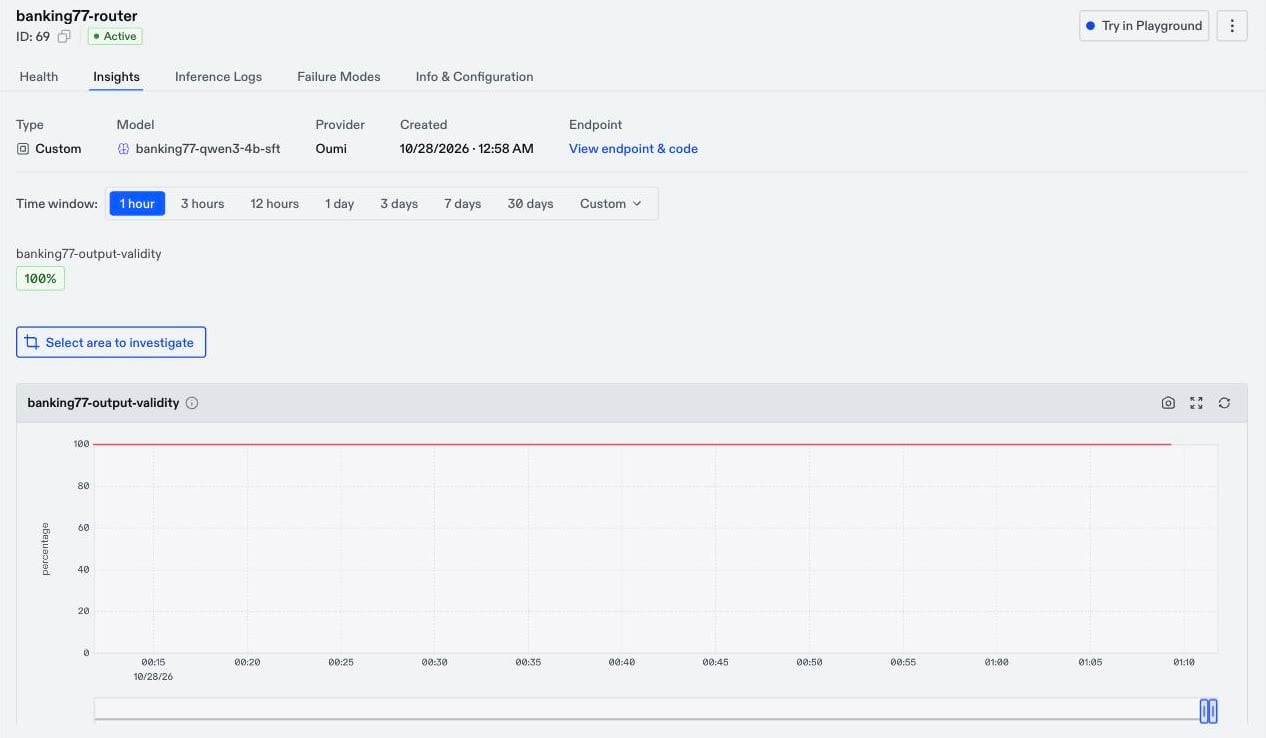
- A drop in score: Investigate the requests behind it. See Investigate a drop.
- A warning badge: The judge failed to score some requests. Hover over the badge to see why. Quota, authentication, rate limit, and timeout errors point at the judge’s provider. An empty response, a judgment outside the evaluator’s labels, or a context length error point at the evaluator’s configuration. A judge failure is not a low score.
- No scored requests: A period with no scored requests can show as a flat line at 100%, so a perfect score is not proof of quality. Select the period and click
View selected logsto confirm that requests were scored. If none were, check the Health tab for traffic, and check that inference logging is on and the sampling rate is high enough for your traffic.
INVESTIGATE A DROP
- On the Insights tab, click
Select area to investigate, and drag across the time range of the drop on any chart. - Click
View selected logs. The Scored Inference Logs table lists each scored request in the range with each evaluator’s judgment. Expand a row to read the judge’s explanation. - Read some low-scoring rows to confirm whether the model or the judge is wrong.
- Click
Run failure-mode analysisto group the failures in the range by cause. The results open on the deployment’s Failure Modes tab.