

WHEN TO USE THE PLAYGROUND
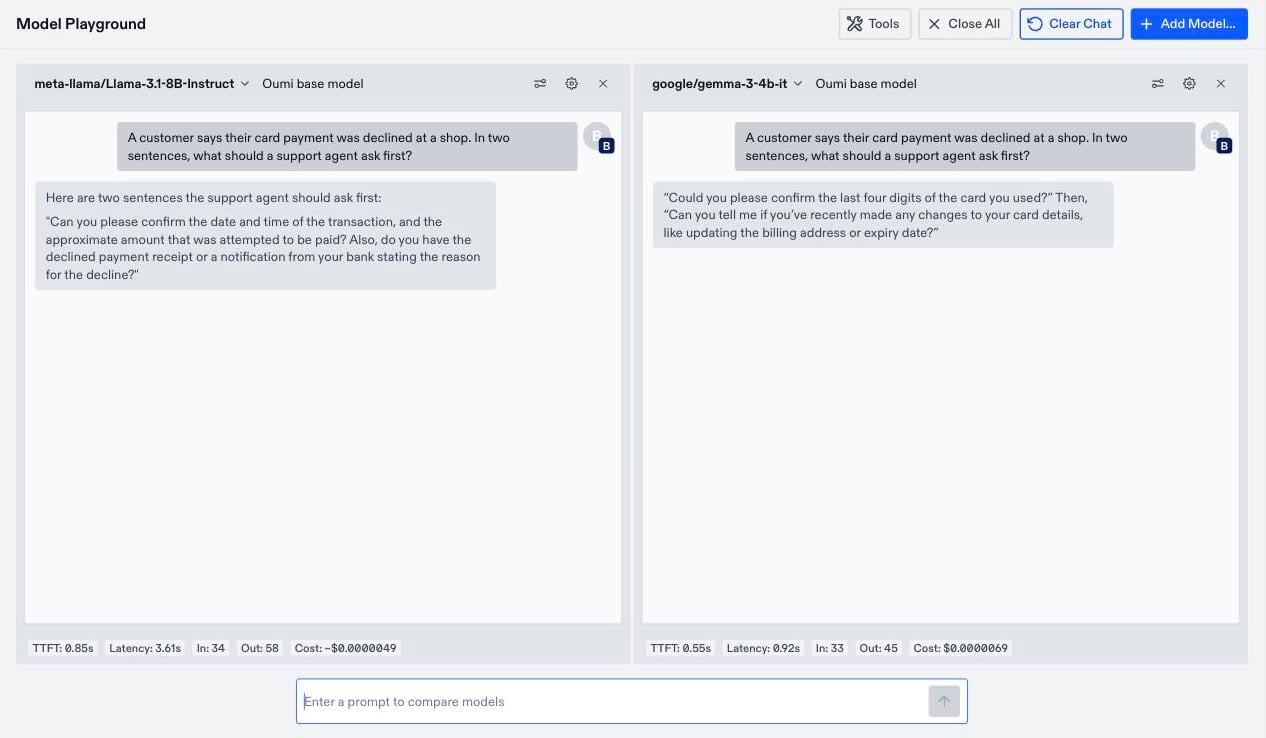
Use the Playground when the question is qualitative and you want an answer right away. It also shows the speed and the estimated cost of each request.
A Playground session is a sanity check before a full evaluation, not a substitute for one. Nothing in the Playground is scored or saved.
WHAT YOU CAN COMPARE
- Your deployments: Every deployment in the project, including external deployments. A panel can chat only with an
Activedeployment. On a deployment that scaled to zero, the first response can take a few minutes while a replica starts. - Oumi base models: Open-source models that Oumi serves directly, so you can try one with no deployment of your own.
- The same model more than once: Add a model twice to compare two system prompts or two sets of parameters against each other.
Try in Playground.
COMPARE MODELS
- Open Playground, and click
Add Model...to add a panel for each model. - Type a prompt and send it. Every panel receives the prompt at the same time and answers on its own.
- Send follow-up prompts. Each panel keeps its own conversation, so each model sees only its own history.
Model changed to divider marks the switch.
Conversations exist only in the page. Leaving or reloading the page loses them.
READ THE RESULTS
Each panel shows chips under its conversation after it answers:TTFT and Latency describe only the latest response. A single request is sensitive to cold starts, prompt length, and load, so read them as a rough sense of speed, not a benchmark. The token counts and the cost grow with every turn, because each turn sends the whole conversation again.
The cost is an estimate based on Oumi’s rates. An OpenAI or Anthropic deployment bills inference to your own provider key, so the provider’s invoice is the actual cost.
SHARE A COMPARISON
The page URL holds the set of models you opened. Send the URL to a teammate, and the Playground opens with the same panels. The URL doesn’t include conversations, system prompts, parameters, or tools.WHAT’S NEXT
Prompts, parameters, and tools
Give each panel its own system prompt and sampling parameters, and let the models call tools.
Evaluations
Score models on a dataset when you need a repeatable comparison.