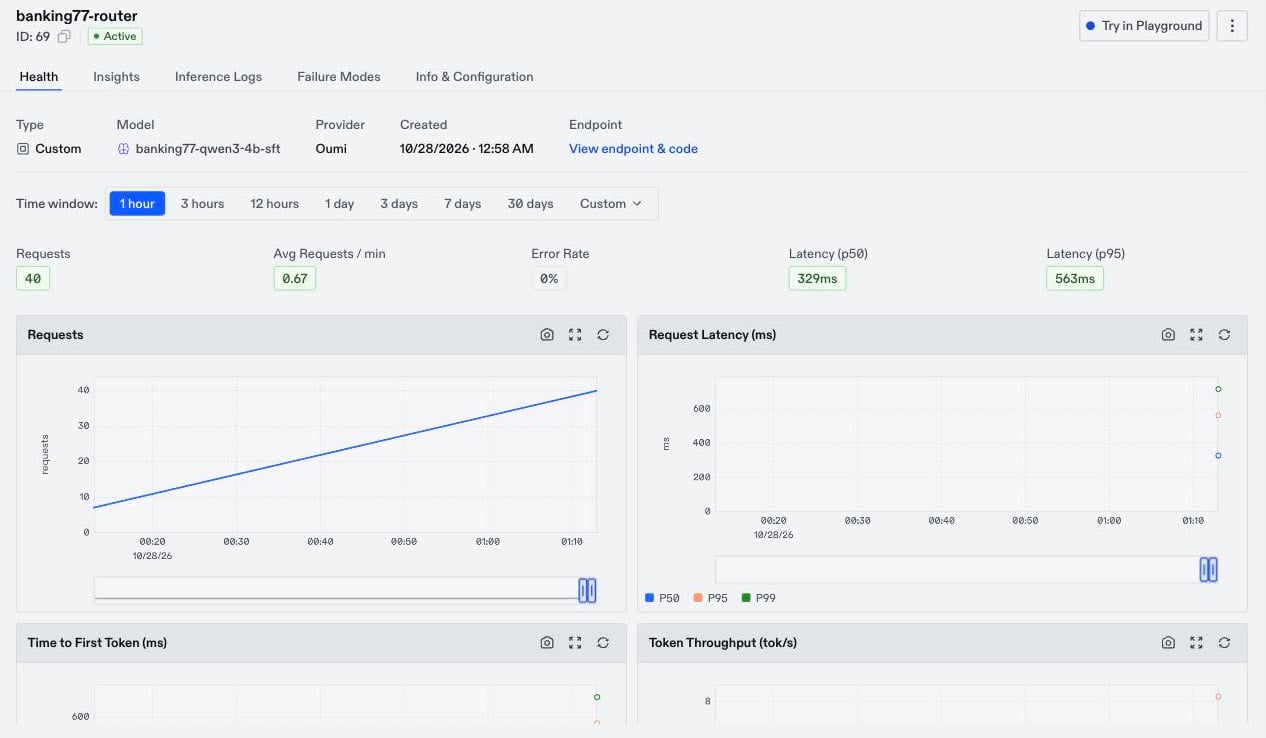
Read a deployment’s traffic, errors, latency, and throughput, and act on what they show
Serving metrics show whether a deployment serves requests reliably and quickly. They come from the inference logs, so every deployment with logging on reports them, with no metrics stack to set up. Serving metrics tell you whether the deployment works. To learn whether its answers are good, use quality monitoring.You can also ask FAiE (Frontier AI Engineer Agent) how a deployment is doing. It reads the same metrics, and with monitoring on, it can tell you whether a problem is operational or a drop in quality.